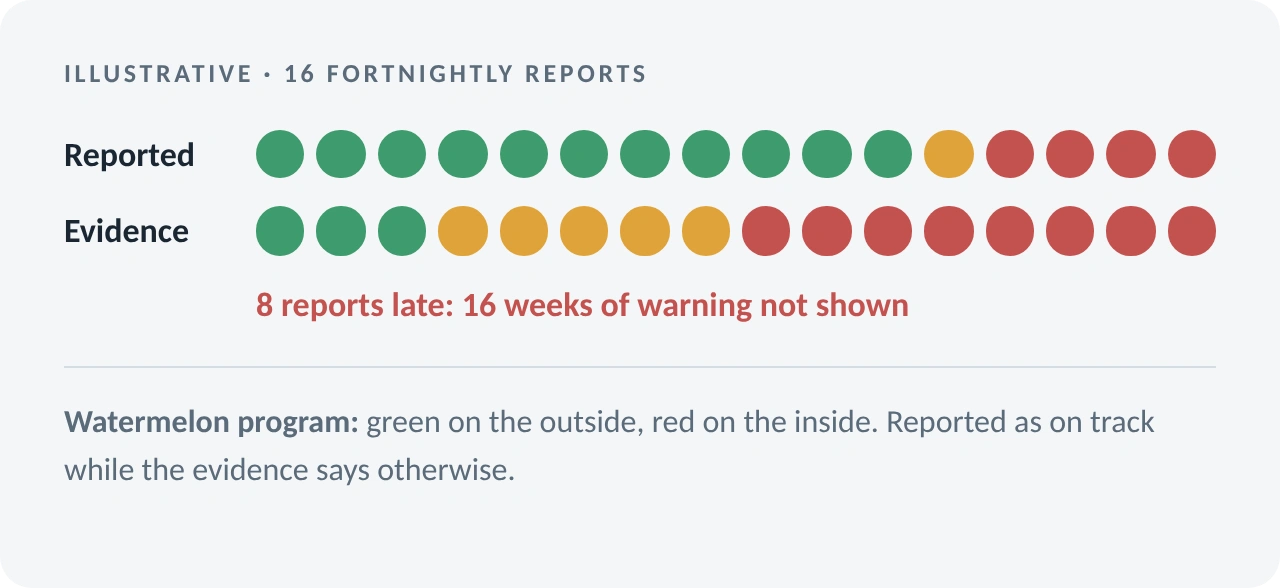
The Watermelon Test: A diagnostic at a depth that wasn't humanly possible before AI
Until now, a program review meant a small team, a sample of documents and a handful of interviews. AI changes that. Our AI workforce reads everything and hears everyone. An experienced human partner, who has run large programs, decides what it means and owns the results.
No one has time to read a year of reports, plans and logs side by side. Our AI workforce does, and it looks at more than 700 factors to assess your project's health.
AI reads everything
Every status report, plan version, RAID log and set of minutes since day one. Not a sample.
AI engages and hears everyone
Everyone who matters, from the sponsor to the front line, is interviewed, written up and compared.
A human owns the answer
Someone who has run large programs decides what the evidence means, and what to fix first.
Four weeks, start to finish
Week 1: Set up
Agree the scope and the questions that matter. Get access to documents, delivery tools and the people we need.
Weeks 2 and 3: Collect and analyse
We read every status report, steering pack, plan version, RAID log and set of minutes. Our AI interviews the people doing the work. Everything is tested against over 700 indicators of program success and twelve green-to-red patterns.
Week 4: Results review
We walk you through what we found and suggested next steps.
Answers the questions that matter
- CFO: "What will this actually cost, and what will it return?"
- COO: "Are we really ready: people, customers, systems?"
- Board or audit: "Can I believe what I am being told?"
- PMO lead: "Do I have all the facts I need?"
- Customers: "What's going to change for me?"
- Regulator: "Have you implemented our new regulation?"